The four single-file HTML results were checked against the rubric shipped with the original prompt. These are one reviewer's visual observations, browser behavior checks, and raw metrics. Generation conditions and real-device performance are not fully verified, so no overall score or formal ranking is published.
/01
Original prompt
Initial test 01 prompt and its matching rubric
/02
Same browser
Chrome 155 · 1920 × 1080 · DPR 1
/03
Full 60 seconds
Recorded separately without speed changes
Behavior checks
Object counts are visible API candidates at seconds 20 / 25 / 30 / 35, not proof that every item is visually distinguishable. Category counts are the minimum across those samples. All four reached and held the 60-second ending; pause froze time and play resumed it.
Model
Object candidates
Categories
Hover shops
Auto cards
GPT-6 Astra
85 / 86 / 86 / 85
7
6/6
3/3
Claude Opus 5.5
74 / 75 / 73 / 70
7
6/6
3/3
Kimi K3.1 Pro
70 / 64 / 72 / 76
5
6/6
3/3
DeepSeek V4.1 Flash
110 / 110 / 113 / 113
5
6/6
3/3
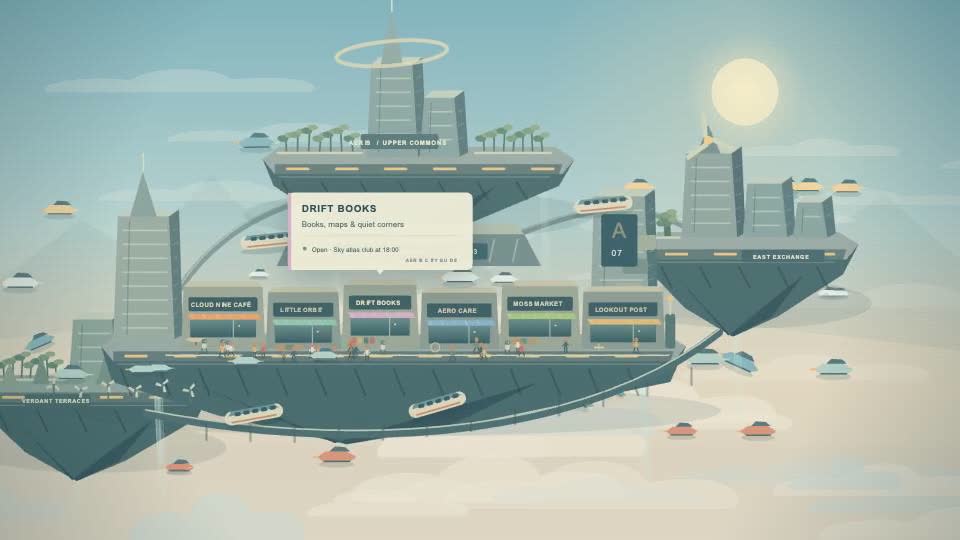
All six shops responded to real pointer hover; three different auto cards appeared for about three seconds each. Touch input and manual priority were also checked.
Observations by model
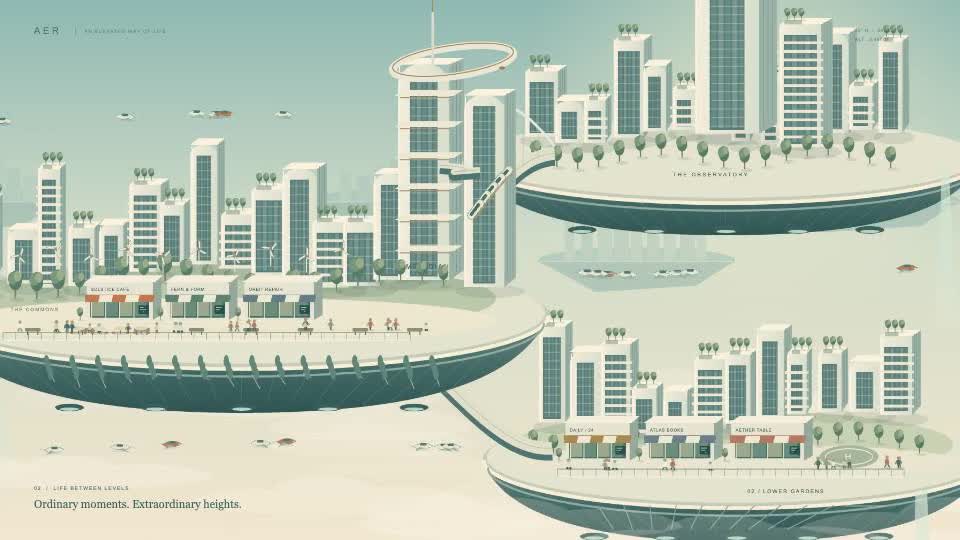
GPT-6 Astra
Codex · reasoning high
Strengths: The three suspended districts read clearly. Soft daylight and clouds support a coherent panorama, with trains, craft, and a large airship carrying the final event.
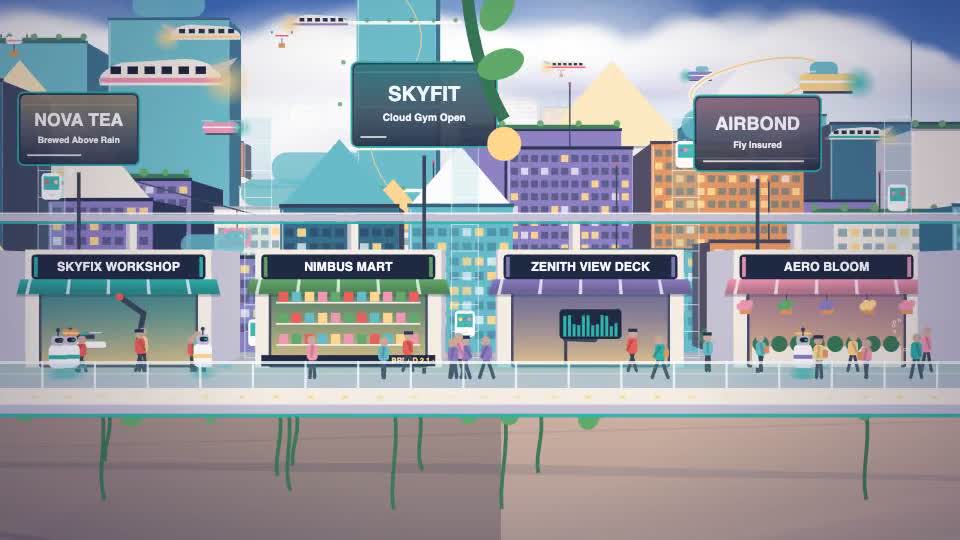
Limits: Tower silhouettes repeat, and shops and people are small in the wide shots.
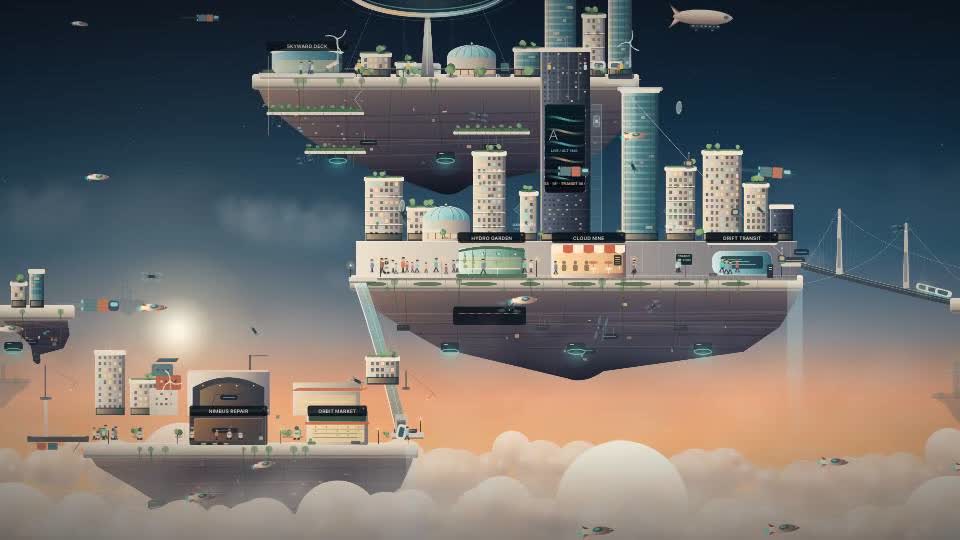
Strengths: Facades, platform undersides, bridges, and traffic carry substantial detail. Dusk lighting gives the scene density, and the airship and final title read clearly.
Limits: Some shops and people are small in the wide view; the central scene is busy, and mid-film camera motion is restrained.
Headless Chrome reported a 16.7–16.8 ms rAF P95 and 0–0.03% of intervals over 50 ms. That cadence alone cannot establish animation quality on a physical display, so the 10-point performance item remains unscored. A frame-by-frame count of visually distinguishable objects also remains open. The rubric therefore precludes an overall score.
Model labels come from the delivered filenames; only the DeepSeek file marks run 2. Independent records of the exact submitted prompts, attempt counts, and repair opportunities are unavailable, so these results are not treated as a controlled model ranking.